DeepSeek V4 Pro 75% Discount: What Replaced It and What V4 Pro Costs Now
DeepSeek made the 75% V4 Pro discount permanent on May 22, 2026, then replaced it with peak and off-peak pricing on August 16, 2026. V4 Pro now costs $0.66 for cache-miss input and $1.98 for output per million tokens off-peak, and $1.32 and $3.96 at peak. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. At peak that is still about 5x cheaper than Claude Opus 5.5 on output, but the $0.435 and $0.87 rates this page first reported no longer exist.
What replaced the 75% discount
DeepSeek’s pricing page now lists two rates per token type for deepseek-v4-pro, and no discount. The change was announced on August 13, 2026, together with the GA release of V4 Pro, and took effect at 16:00 UTC on August 16, 2026. DeepSeek said the peak and off-peak split is meant to allocate resources more reasonably.
| Token type | Off-peak (per 1M tokens) | Peak (per 1M tokens) |
|---|---|---|
| Input (cache hit) | $0.022 | $0.044 |
| Input (cache miss) | $0.66 | $1.32 |
| Output | $1.98 | $3.96 |
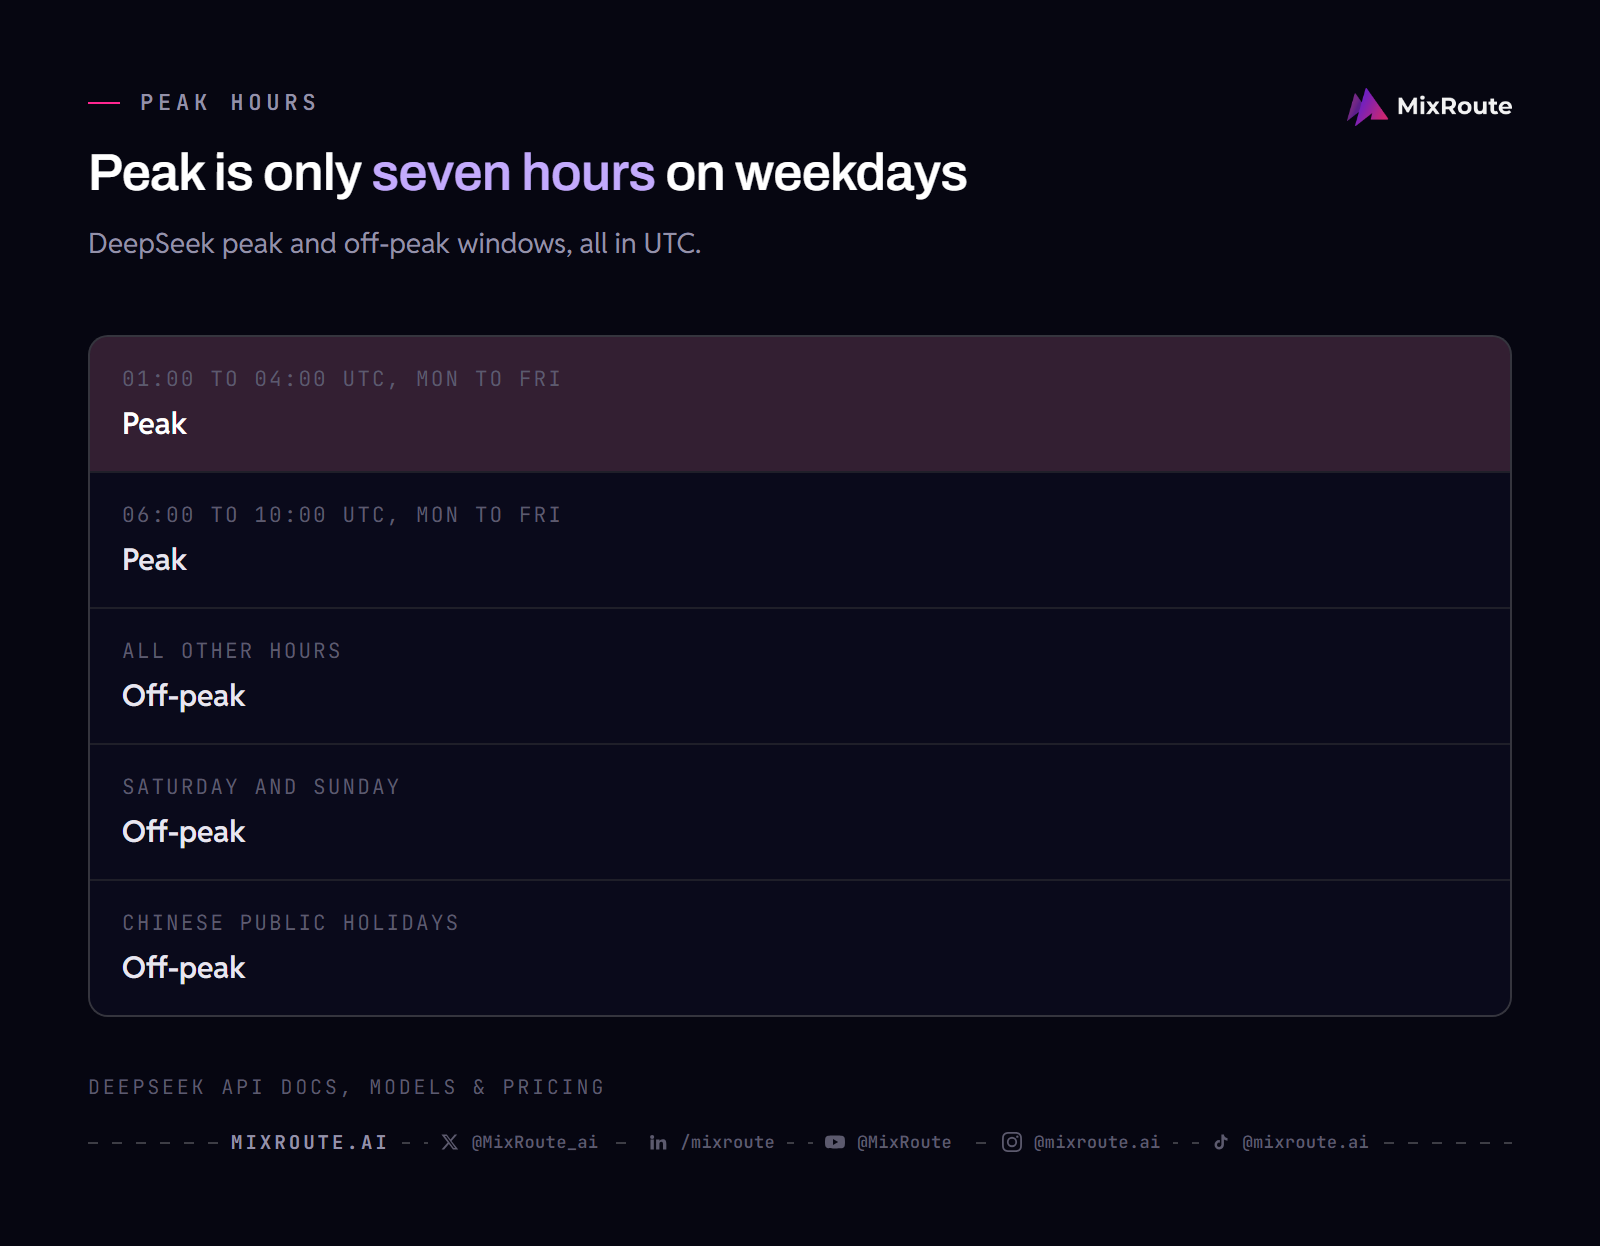
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. All other hours are off-peak, including weekends and Chinese public holidays in full. Off-peak rates are half of peak rates. A batch job that does not need an answer right away can wait for the cheaper window.
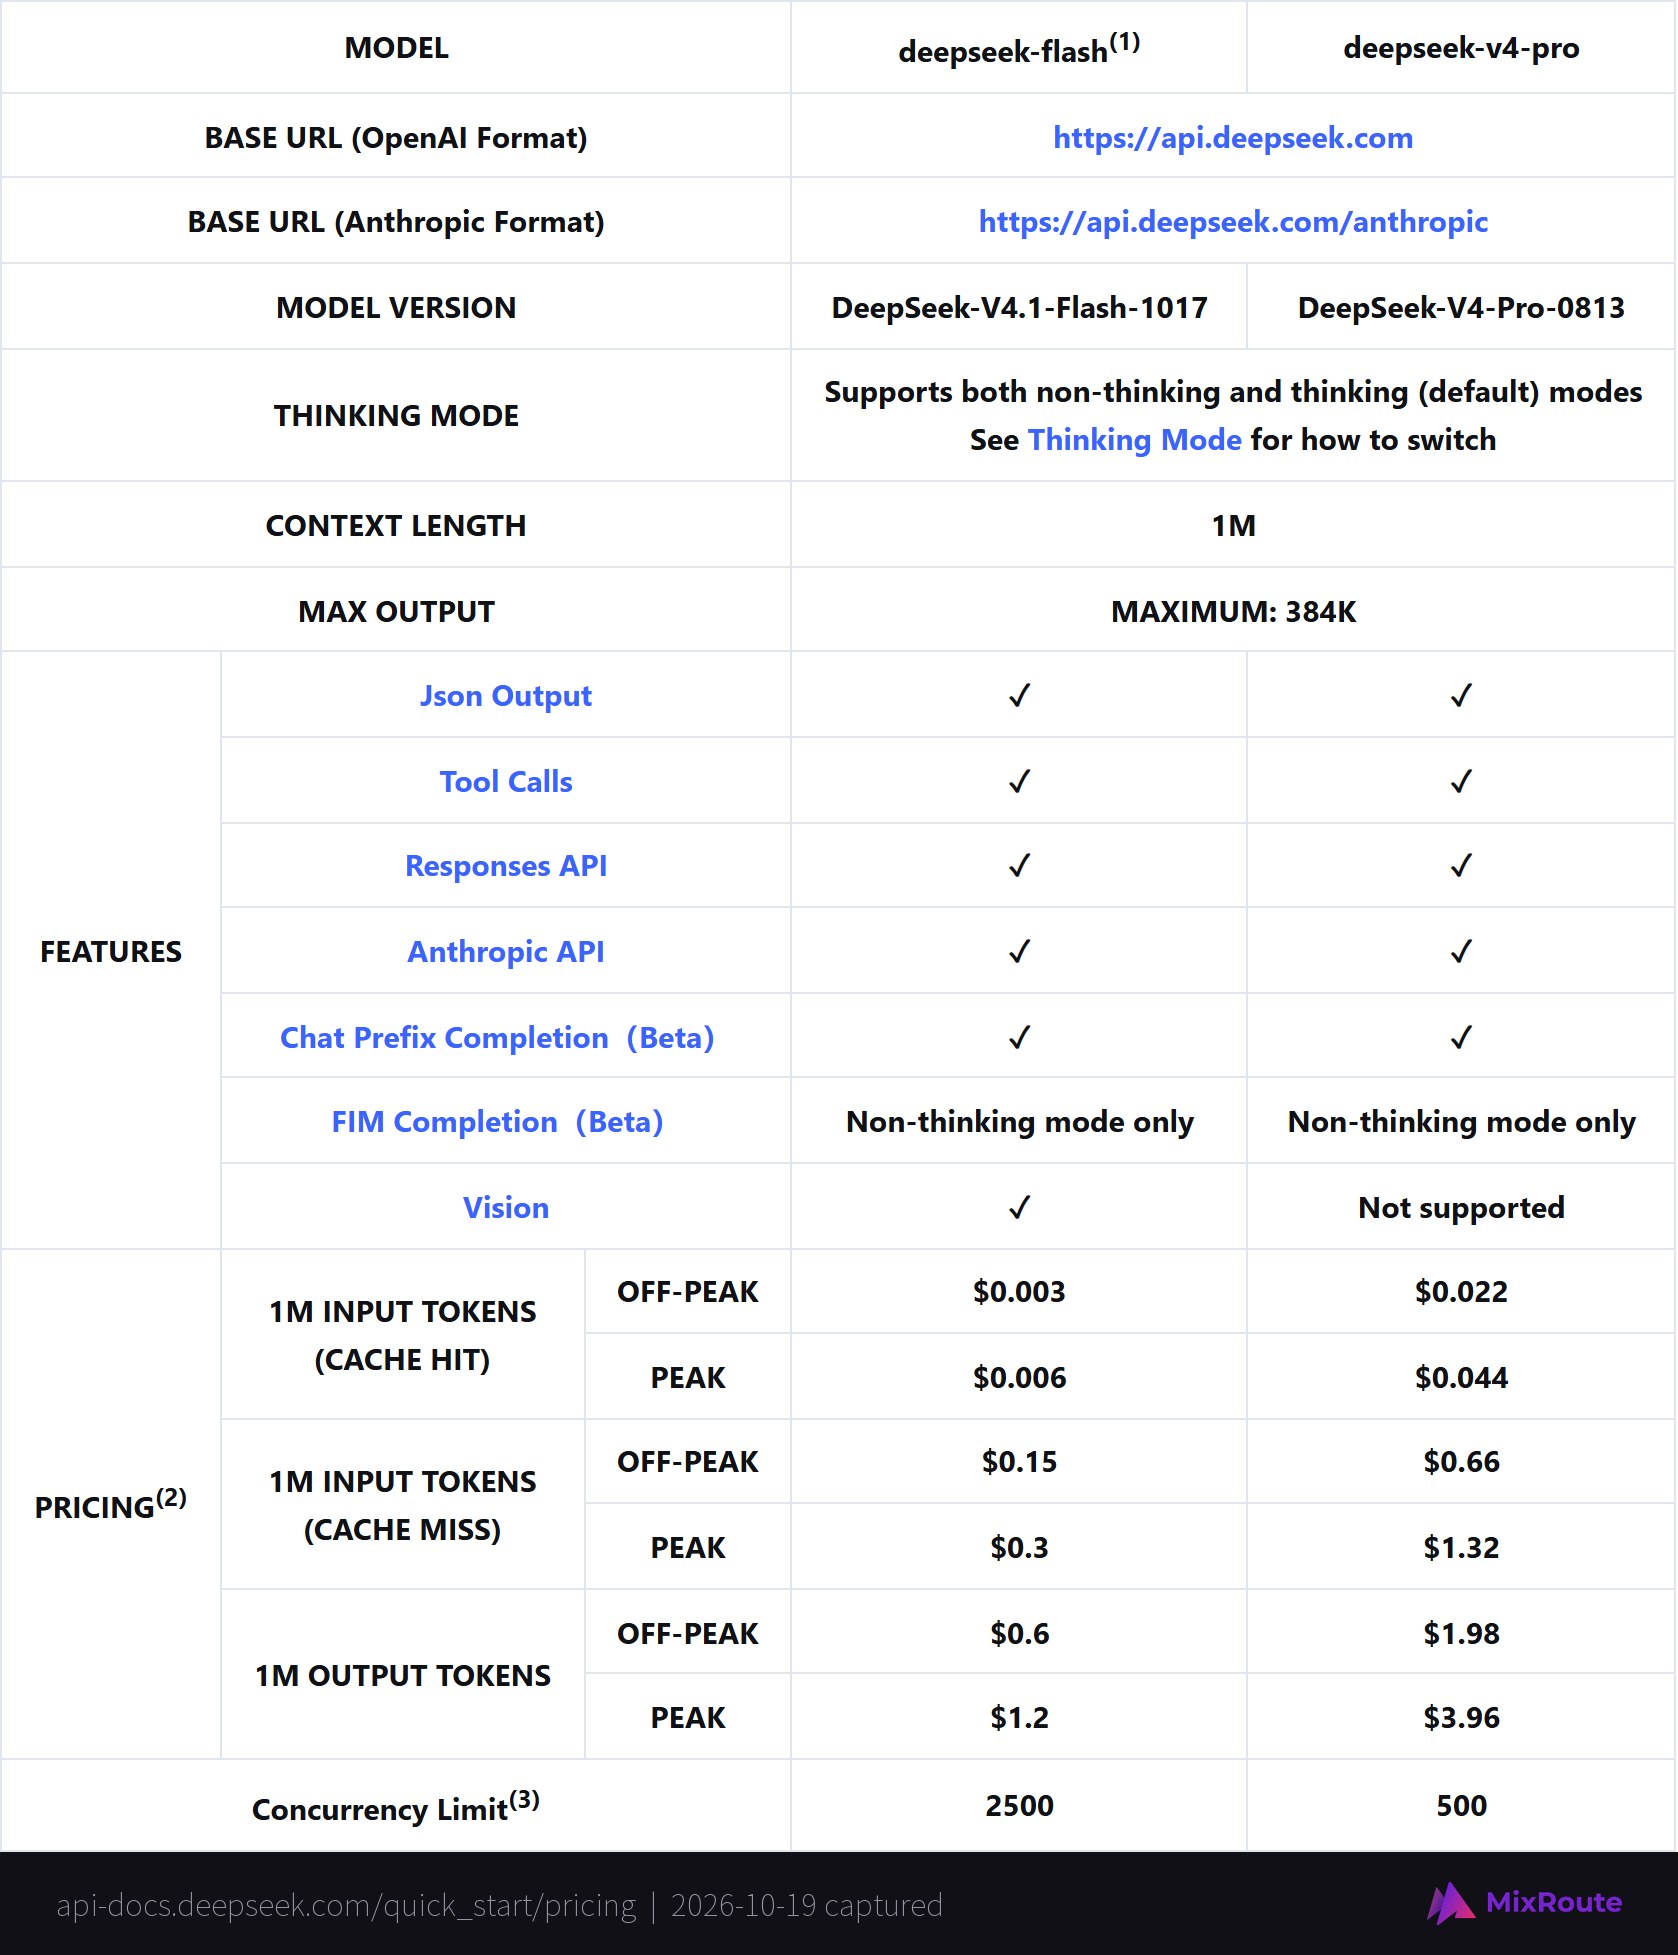
These are DeepSeek’s own prices, read from its pricing page on October 19, 2026. DeepSeek’s September 10 release note first said all deepseek-v4-pro requests would route to V4.1 Flash from September 14 until a V4.1 Pro launches. Its change log for the same day reversed that: V4 Pro stays available after September 14, 2026 with billing unchanged, and DeepSeek will give notice of any further change.
What was announced
On May 22, 2026, DeepSeek announced on its X account and API docs that the 75% discount on V4 Pro, originally scheduled to expire May 31, 2026, was now the permanent rate. The promotional pricing became the official pricing.
As of May 24, 2026, the permanent pricing for deepseek-v4-pro was:
| Token type | Price on May 24, 2026 (per 1M tokens) | Original price | Discount |
|---|---|---|---|
| Input (cache hit) | $0.003625 | $0.0145 | 75% off |
| Input (cache miss) | $0.435 | $1.74 | 75% off |
| Output | $0.87 | $3.48 | 75% off |
Several pages still quote these rates as current. Since August 16, 2026 they are not: cache-miss input is 1.5x higher off-peak and 3x higher at peak, and output is about 2.3x and 4.6x higher.
What V4 Pro actually is
DeepSeek V4 Pro launched April 24, 2026 as a 1.6 trillion parameter Mixture of Experts model with 49B active per forward pass. The specs that matter for cost planning:
- 1M token context window and up to 384K output tokens per request.
- Text only. DeepSeek’s pricing page lists vision as not supported for V4 Pro.
- JSON output, tool calls and the Responses API are supported, and thinking mode has three effort levels: low, high and max.
- The GA release on August 13, 2026 (DeepSeek-V4-Pro-0813) reported Terminal Bench 2.1 at 87.9 and DeepSWE at 62.7.
- DeepSeek’s concurrency limit for V4 Pro is 500.
DeepSeek V4.1 Flash costs less than a third of V4 Pro
V4.1 Flash, released September 10, 2026, is priced at $0.15 for cache-miss input and $0.60 for output off-peak, and $0.30 and $1.20 at peak. Against V4 Pro that is under a third of the price on both input and output. Cache-hit input is $0.003 off-peak and $0.006 at peak.
It has a 1M token context window, 384K max output and image input, which V4 Pro lacks. DeepSeek cites tests by multiple parties that put V4.1 Flash ahead of V4 Pro on performance, cost, speed and total runtime, so test it on your own traces before paying for the larger model. On DeepSeek’s API it is called deepseek-flash. The MixRoute model ID is deepseek-v4.1-flash.
How V4 Pro compares at today’s price
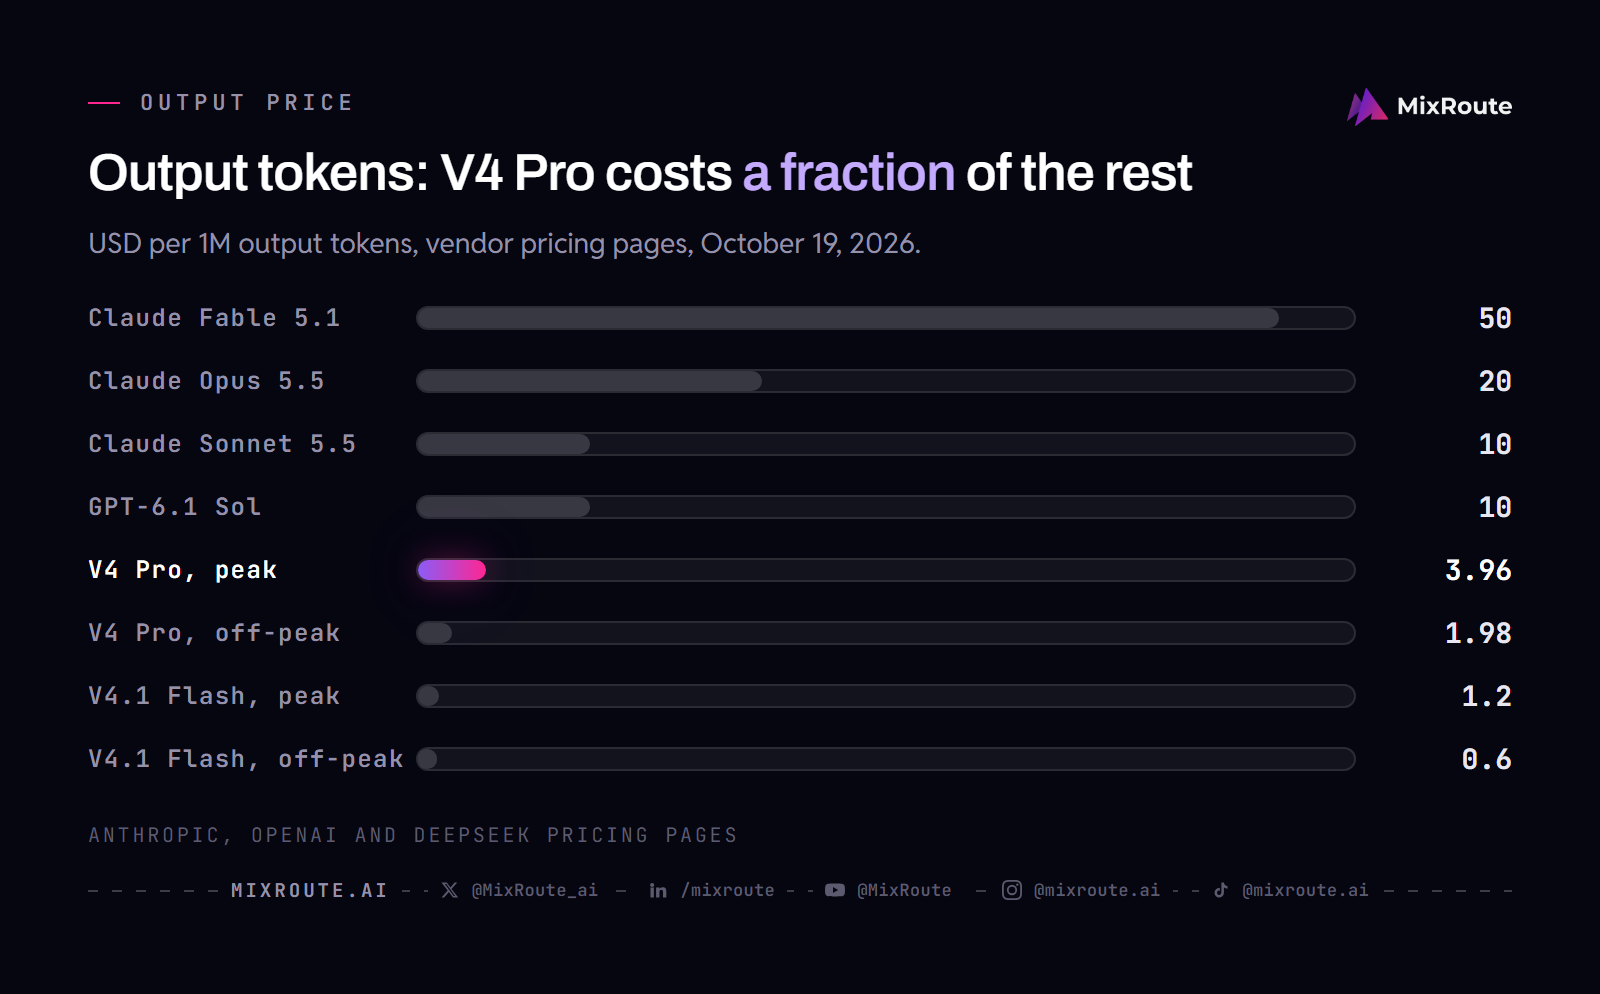
V4 Pro is about 3x cheaper than Claude Opus 5.5 on input and about 5x cheaper on output at peak, and about 6x and 10x cheaper off-peak. The table lists each vendor’s own price per million tokens as of October 19, 2026.
| Model | Input ($/1M) | Output ($/1M) | Cached input ($/1M) |
|---|---|---|---|
| Claude Fable 5.1 | $10.00 | $50.00 | $0.25 |
| Claude Opus 5.5 | $4.00 | $20.00 | $0.20 |
| Claude Sonnet 5.5 | $2.00 | $10.00 | $0.10 |
| GPT-6.1 Sol (up to 272K input) | $2.00 | $10.00 | $0.10 |
| DeepSeek V4 Pro, peak | $1.32 | $3.96 | $0.044 |
| DeepSeek V4 Pro, off-peak | $0.66 | $1.98 | $0.022 |
Against Claude Sonnet 5.5 and GPT-6.1 Sol, V4 Pro is about 2.5x cheaper on output at peak and about 5x cheaper off-peak. GPT-6.1 Sol prompts over 272K input tokens are priced at 2x input and 1.5x output for the full request, so the gap widens on very long prompts. Cached input is the largest difference: V4 Pro’s cache-hit rate is a fraction of the $0.10 to $0.25 the other models charge.
How the permanent price was replaced
The permanent rate was announced on May 22, 2026 and replaced on August 16, 2026. The order of events, from DeepSeek’s change log and news posts:
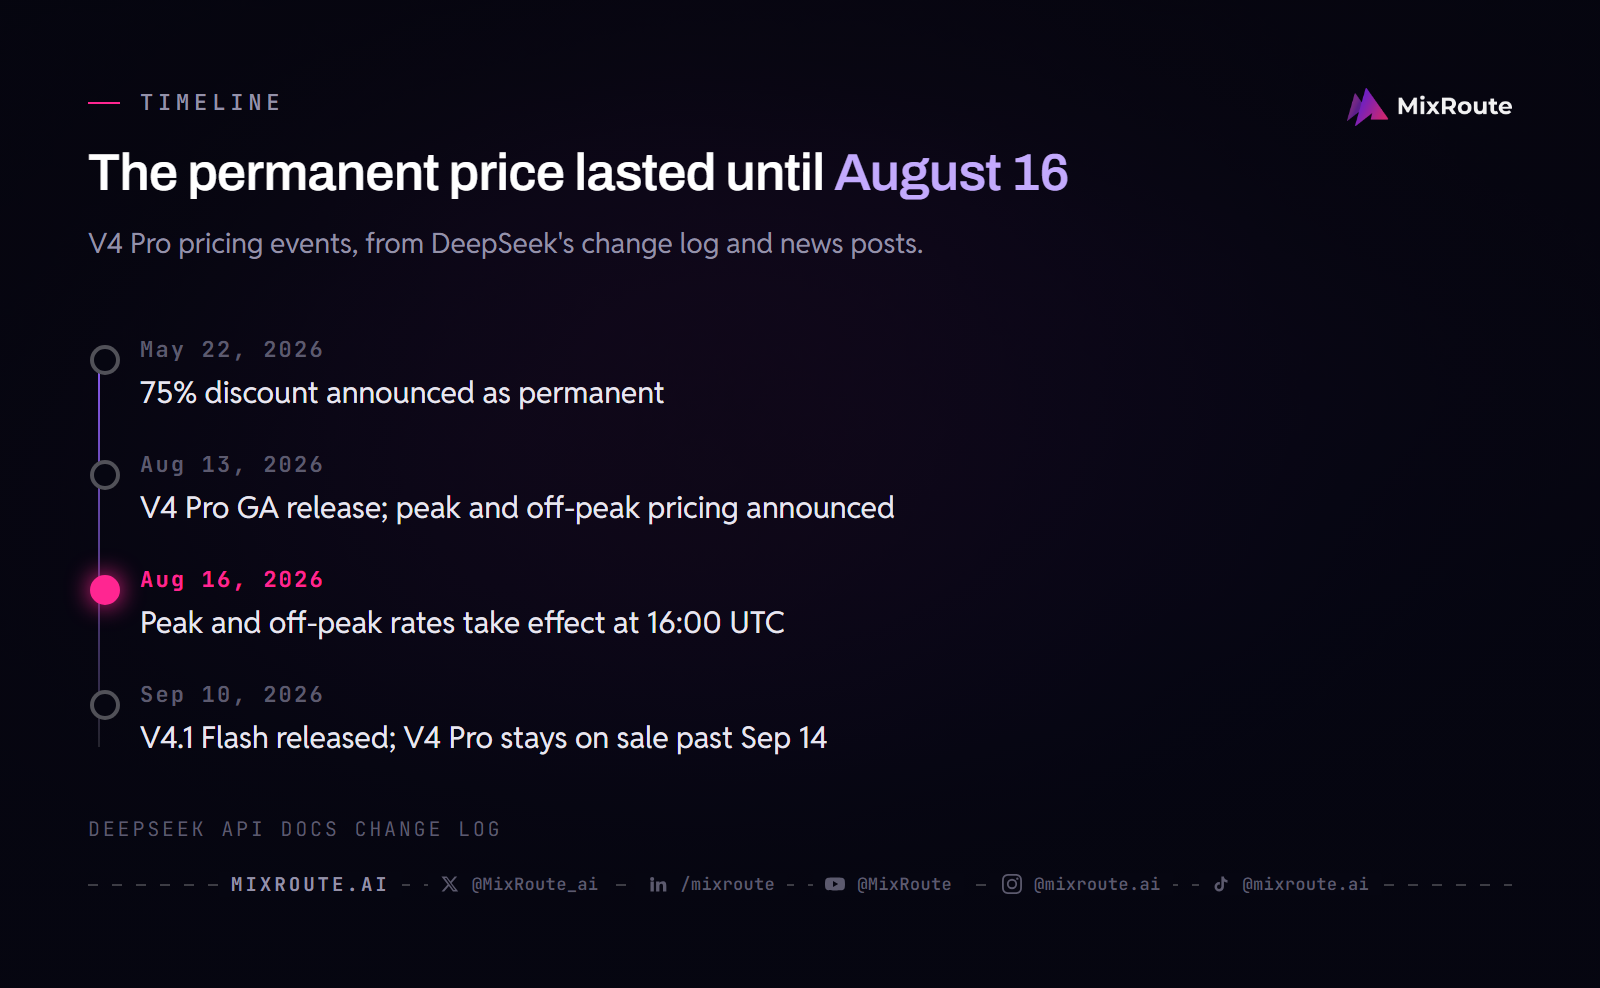
DeepSeek’s change log gives resource allocation as the reason for the peak and off-peak split. The same announcement covered the GA version of V4 Pro, and on September 10 V4.1 Flash followed with lower API prices. A budget built on $0.435 and $0.87 per million tokens needs recalculating with the table above.
What this means for builders
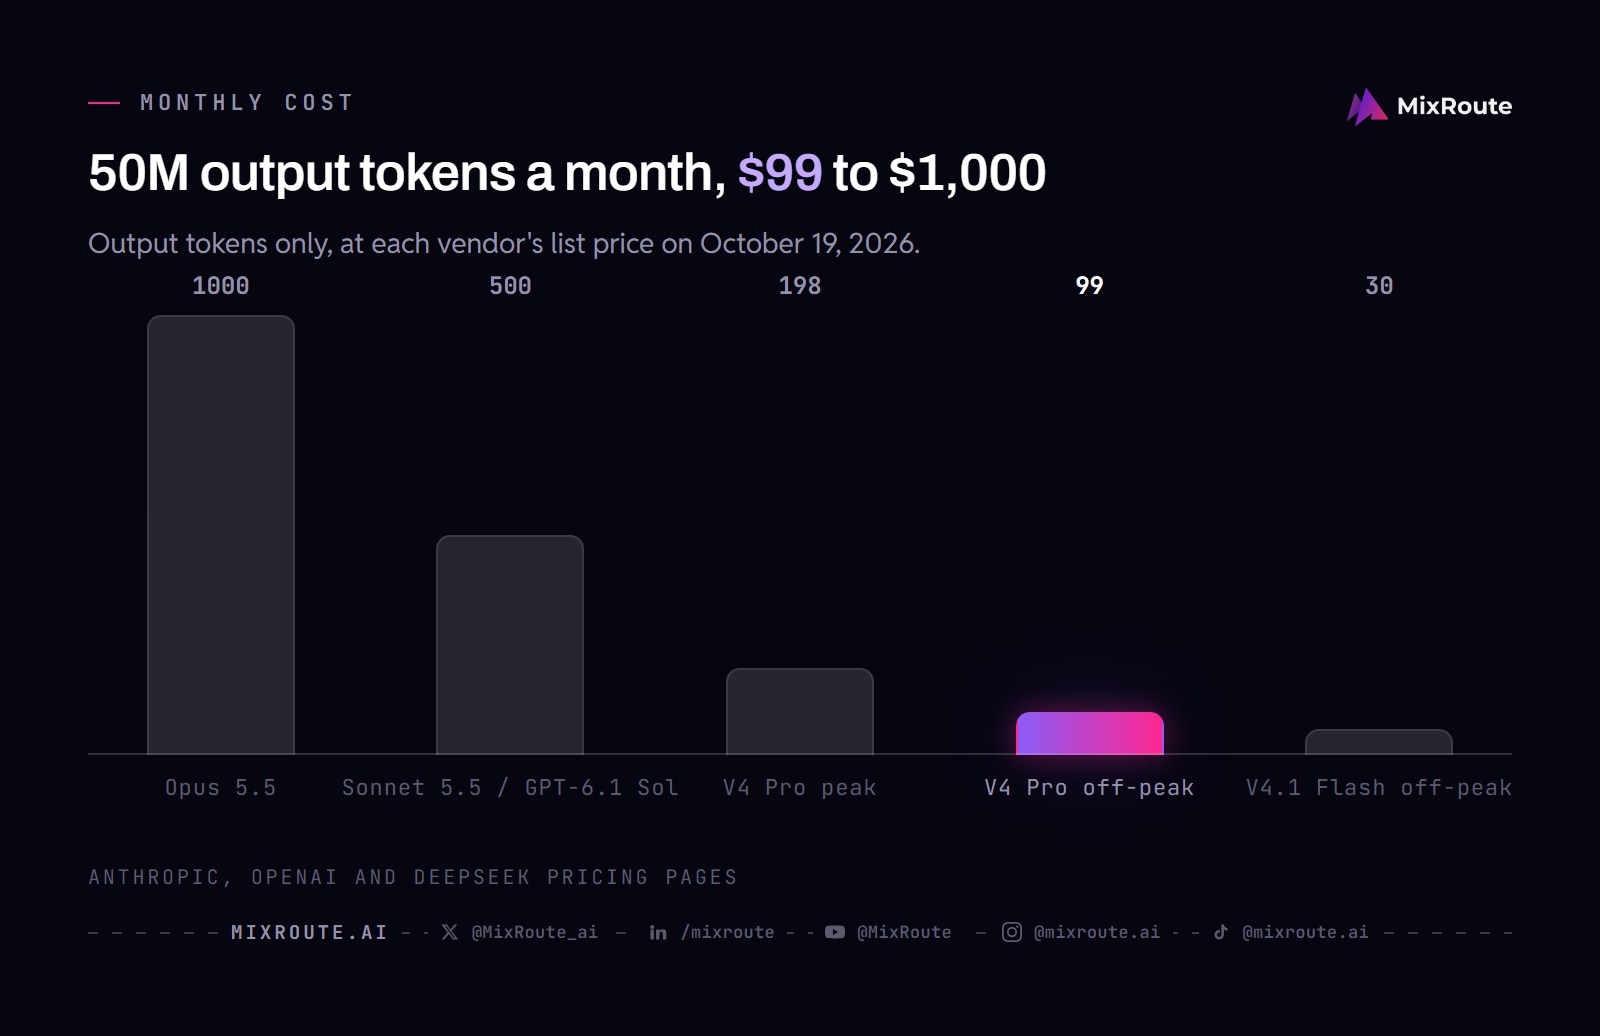
Agent workloads are still far cheaper on V4 Pro, just not at the old floor. A long-running code review agent producing 50M output tokens a month costs $1,000 on Claude Opus 5.5 and $500 on Claude Sonnet 5.5 or GPT-6.1 Sol. The same output costs $198 on V4 Pro at peak and $99 off-peak. On V4.1 Flash it costs $60 at peak and $30 off-peak. These figures count output tokens only.
Schedule the work that can wait. Nightly evaluation runs, bulk summarization and backfills do not need an answer at 09:00 UTC on a Tuesday. Weekends and Chinese public holidays are off-peak all day, so those jobs cost half as much as the same job during peak hours.
Per-request model choice is now a cost lever. Send the long agent loop to V4.1 Flash or V4 Pro and the final review pass to Claude Opus 5.5, and the blended cost drops while the expensive model only sees the last step. Measure quality on your own tasks before moving any production traffic.
MixRoute gives you 250+ models through a single OpenAI-compatible endpoint, and deepseek-v4-pro and deepseek-v4.1-flash are both in the model catalog. The same key and base URL you use for GPT or Claude work for them, so switching is a change of model ID. You can start building on MixRoute with a new key.
from openai import OpenAI

client = OpenAI(
    base_url="https://api.mixroute.ai/v1",
    api_key="YOUR_MIXROUTE_KEY"
)

response = client.chat.completions.create(
    model="deepseek-v4-pro",
    messages=[{"role": "user", "content": "Refactor this function..."}]
)
FAQ
What is DeepSeek V4 Pro? A 1.6 trillion parameter Mixture of Experts model with 49B active per forward pass and a 1M token context. It launched April 24, 2026, and its GA version DeepSeek-V4-Pro-0813 followed on August 13, 2026.
Is the DeepSeek V4 Pro 75% discount still available? No. DeepSeek’s pricing page lists only peak and off-peak rates since August 16, 2026. Off-peak cache-miss input is $0.66 and output is $1.98 per million tokens, which is half of the peak rates of $1.32 and $3.96.
How much does DeepSeek V4 Pro cost as of May 24, 2026? On that date it was $0.003625 per million tokens on cache hit input, $0.435 on cache miss input, and $0.87 per million output tokens. Today the cheapest rate is off-peak: $0.022 cache hit, $0.66 cache miss and $1.98 output.
Is DeepSeek V4 Pro cheaper than Claude Opus 5.5 or GPT-6.1 Sol? Yes. V4 Pro output costs $3.96 at peak and $1.98 off-peak, against $20 for Claude Opus 5.5 and $10 for GPT-6.1 Sol up to 272K input tokens. That is about 5x and 2.5x cheaper at peak, and about 10x and 5x cheaper off-peak.
When did the 75% discount become permanent? DeepSeek announced it on May 22, 2026, ahead of the May 31, 2026 expiry. The permanent rate was replaced when peak and off-peak pricing took effect at 16:00 UTC on August 16, 2026.
What are DeepSeek’s peak and off-peak hours? Peak is 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. Every other hour is off-peak, including all of Saturday, Sunday and Chinese public holidays. Convert to your time zone before scheduling batch jobs.
Does the discount apply to prompt caching too? It did. Cache-hit input fell from $0.0145 to $0.003625 per million tokens under the 75% discount. It is now $0.022 off-peak and $0.044 at peak, still well below the $0.10 to $0.25 that Claude Opus 5.5, Claude Sonnet 5.5, GPT-6.1 Sol and Claude Fable 5.1 charge for cached input.
How do I switch from Claude or GPT to DeepSeek V4 Pro without rewriting my code? Through an OpenAI-compatible endpoint. With MixRoute, you change the model name in your existing OpenAI SDK call to deepseek-v4-pro. The same key and base URL cover the other models in the catalog.